
robots.txt for AI assistants: who to allow, and who you must not block
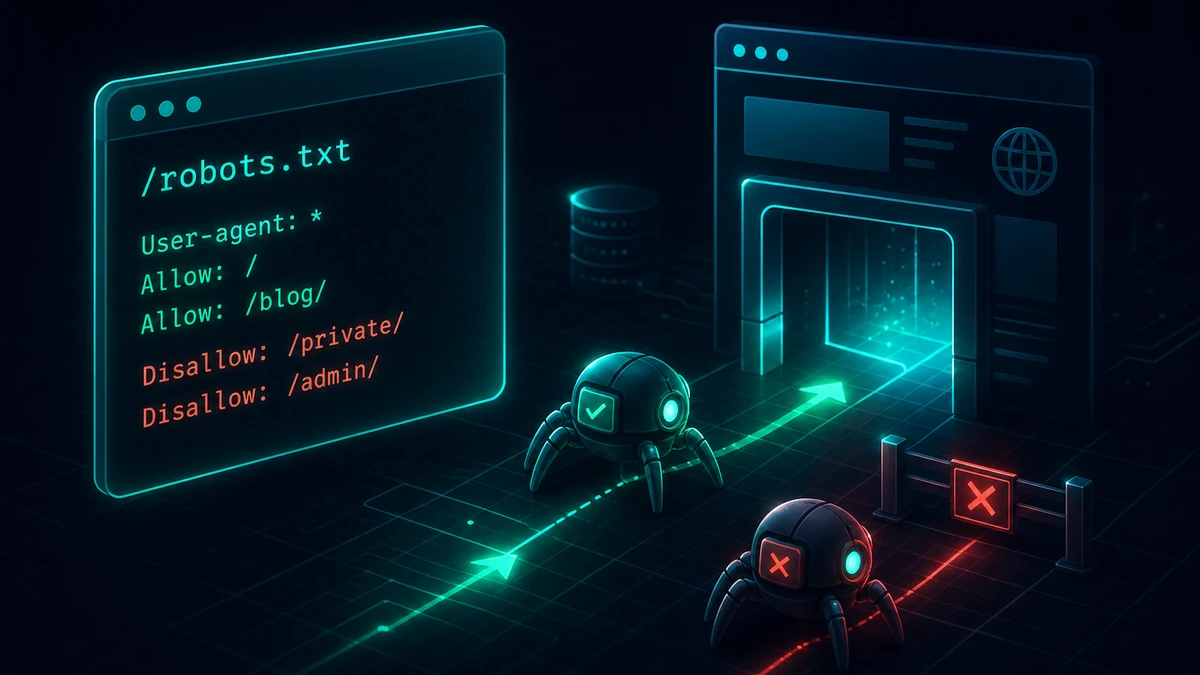
robots.txt is the first file bots open. One wrong Disallow, and Alice stops seeing updates, ChatGPT never finishes the price list, and you spend weeks looking for "why we are not in the recommendations". Not in the WordPress code. Not in "the algorithm". In one line someone added "because a chat said so".
Below: who to allow if you want to show up in AI answers, who you must not cut by accident, what owners do to themselves, and how to check the file before you edit it. robots.txt is the switch. After it, the model either reads you or learns from a competitor.
Why AI assistants care about robots.txt
Classic search engines have read robots.txt for a long time. LLM crawlers follow the same logic: the file says where they may go and where they may not. It is not a lock against hacking and it is not an NDA. It is a polite rule for robots. Break it, and the robot stops visiting, or visits less. For a business that means fewer mentions in answers from Alice, Yandex Neuro, and ChatGPT.
WAF, Cloudflare, nginx rules, and "anti-parsing" in the hosting panel live separately. They cut bots even when robots.txt looks correct. So you check the file and the real server response. In a Leadsy audit that is one block: technical access, not a guess from a notebook.
A lot of people think: "the site is open, why do we need the file". The bot still asks permission. If the answer is ambiguous, or www and non-www disagree, the crawler picks the safe option. Often that option is "do not go".
Who to allow if you want leads from AI answers
For visibility in Russia, YandexBot is critical: Alice, Yandex Neuro, maps, and classic search. For Western models: GPTBot (OpenAI), ClaudeBot (Anthropic), PerplexityBot, Google-Extended (Gemini). GigaChat uses its own crawlers. The list changes. The rule is simple: if you want answers on a platform, its bot has to read the public pages with prices, FAQ, and contacts.
- Yandex: Alice, Yandex Neuro, the index, maps;
- GPTBot: ChatGPT and OpenAI products;
- ClaudeBot: Claude;
- PerplexityBot: Perplexity;
- Google-Extended: Gemini and Google's extended services.
Blocking everyone "so they do not steal the copy" is a popular mistake. People and competitors already read the copy. Without bots there is nothing to build a recommendation from. The competitor with open access gets the leads. You do not. No click, no call, as in the article on Alice.
Five signs robots.txt is cutting you off
- The file has User-agent: * and Disallow: /, or the root is closed with no Allow for the paths you need.
- You copied a template from another site. The paths do not match your CMS, and the Disallow stayed.
- You blocked GPTBot "because this is Russia", and the host blocks a wider class of bots.
- www and non-www serve different robots.txt files. The bot visits one mirror, the file lives on the other.
- After the edit you did not check. The audit shows red technical access, and the notebook says "all fine".
Fail one item and you are not "a bit lower in search". You are missing from what the model knows about the niche. A person asks Alice and hears someone else's name.
Blocking GPTBot "because this is Russia" is a mistake for a clinic, a salon, or a delivery service: some clients ask ChatGPT about services in Russia. The audit check is whether the bot reaches the FAQ and the prices.
GigaChat and Perplexity separately: their crawlers also have to read the public price list if you want mentions there. A bulk ban of "everyone extra" cuts channels you forgot about.

What people do themselves, and where it breaks
Forums still say: "block GPTBot", "copy robots from a SaaS", "add Disallow on everything extra". It sounds fast. In practice it costs weeks of visibility.
A paste from someone else's template
You took a file from an IT company: /docs/, /api/, /blog/dev/. You run a beauty salon. Those paths do not exist, but the template had Disallow: /. The site is closed to everyone. The owner did not touch the file for months. They were also missing from Alice tests.
A ban on "extra" bots
GPTBot, ClaudeBot, and "the ones we do not need" were closed. The general user-agent was hit too, or the WAF cut Yandex. Ads keep running. Recommendations go quiet.
Disallow by substring
Disallow: /private also cuts /private-clinic if the server is set up that way. You closed "the back office" and closed half the services.
Edits with no saved copy and no audit
One line on Friday night. On Monday, updates disappeared from Yandex Neuro. A rollback is not one minute: you need a recrawl and the listings lined up again.
A conflict with llms.txt
llms.txt points at /price/. robots.txt blocks /price. You built the contradiction yourself. The AI assistant does not argue. It goes to the competitor. More: the llms.txt article.
What you can close safely
It makes sense to close the admin, the cart, the account area, UTM filters, duplicates with ?sort=, test subdomains, and drafts. Do not close: services, prices, FAQ, contacts, about, case studies.
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /cart/
Disallow: /checkout/

User-agent: Yandex
Allow: /

User-agent: GPTBot
Allow: /
An example. Do not copy it blind. Paths depend on your CMS. On Tilda, robots often live in the site settings. On Bitrix, the file sits in the root after publish. Check the old test subdomain: a copy of the prices often sits there with Disallow: /.
llms.txt and the sitemap, together
llms.txt points at important URLs. robots.txt allows or blocks crawling. The sitemap suggests the structure. The three files have to say the same thing: public commercial pages are open. A mismatch is why the bot never reaches the price list.
noindex and Disallow are different layers. noindex tells search not to put the page in the index. Disallow says do not visit the URL. A page can be closed to the index while a bot is also blocked on the server. You need both in your head.
How to scare a bot off in one evening
You can. In practice it looks like this:
- Disallow: / after the admin was hacked, and nobody opened it again.
- A sharp file change with no saved copy of the old version.
- llms.txt says "read the price list", robots blocks /price/.
- A WAF with "anti-parsing" cuts YandexBot along with the attackers.
- Edits with no audit. A month later you cannot tell what broke visibility.
The bot does not take offense. It stops treating you as a source. Clients keep asking Alice and hearing other names.
Worse when the content is what got "scared": services were deleted, prices changed on the site, and Yandex Business still shows last year. Alice sees the conflict and picks the business whose numbers match.
A workable order, and where to start
Do not edit robots.txt by eye. Take a snapshot first. A free Leadsy audit shows which bots get through, and whether the block is in the file or on the WAF. Save the old version in git or in a note.
- Express audit: GEO Score, technical access, YandexBot and GPTBot.
- Compare www and non-www, http and https.
- Specific Allow rules, not a bulk ban of "everyone extra".
- Line it up with llms.txt and the sitemap.
- Audit again in 2 to 4 weeks.
A small test: example.com/robots.txt in a private window, the price list from a phone with no VPN, three queries in Alice. If that disagrees with the report, dig into the WAF. Do not start writing SEO copy.
If you already closed the whole site, open access again, line up the listings and the FAQ, and give the crawlers time. The timeline is weeks, not hours. Pricing: the pricing page. On AIO: AIO vs SEO.
robots.txt is the visibility switch. A mistake is cheaper to avoid than to undo. Numbers from the audit first, then edits. Without a snapshot, any advice from a chat is a gamble with the domain.
Typical case: a friend said to block a few user-agents so you "do not expose the structure". Organic leads did not drop. There were none. Mentions in Alice tests did disappear. They came back only after an audit, the blocks removed, and the listings lined up. Weeks, not a weekend.
If nothing changes in the first three days after you open the site, that is normal. Crawlers do not run on your calendar. Stable access first, then the FAQ and prices, then patience.
Leave robots.txt alone until you have a snapshot. Do not copy someone else's file. Audit first. You will see whether YandexBot or GPTBot is blocked right now.
A short checklist: the file opens in a private window, www matches non-www, the price list is readable on a phone, three queries in Alice, and the report has no red flags or you have a plan for them. Fifteen minutes before any edit.
"Our robots file looks fine" and "bots get through" are different things. The file can look clean while the WAF cuts traffic. Recommendations stay quiet. Leadsy checks both layers.
A free audit does not force you to buy an action plan. It does take the domain off the gambling table. One Disallow: / costs more to roll back than any plan.
Who edits the file: a developer, or an admin with access to the root. A marketer does not touch it without a snapshot in the audit. The owner confirms that bots are allowed in.
After a host or CDN change, check robots again. The WAF may have turned on by default. The file is the same. The bots do not arrive.
User-agent: * plus separate blocks for Yandex and GPTBot: check that the specific rules do not contradict the general ones. A bot reads its own block, not an average.
A test subdomain staging.example.com with Disallow: / sometimes gets indexed on its own. Close it to the public, or redirect it to production.